
Introduction
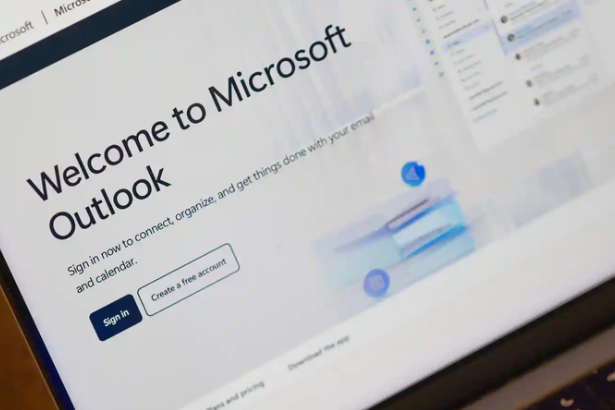
The Microsoft outage has exposed just how dependent the modern workplace has become on cloud-based technology. Millions of people across the world have faced problems accessing Outlook, Microsoft Teams, Microsoft 365 and Copilot after a major infrastructure disruption affected Microsoft’s services on November 12 and continued into November 13, 2026.
For businesses, schools, government agencies and everyday users, the disruption was more than an inconvenient email failure. It interrupted meetings, delayed business communications and affected services that organizations rely on to operate.
According to reporting by Reuters, Downdetector recorded nearly 130,000 reports of Microsoft 365 problems across 74 countries and territories during the disruption. Microsoft acknowledged that servers had unexpectedly become unavailable, creating additional pressure on the remaining infrastructure.
The company initially reported limited progress before later describing positive results from its recovery efforts.
But the incident raises a bigger question: how can one of the world’s largest technology companies experience such a widespread failure across services used by hundreds of millions of people?
Background and Context: Why Microsoft 365 Matters
Microsoft has built one of the world’s most deeply integrated workplace technology ecosystems.
Its Microsoft 365 platform connects several essential business applications, including:
- Outlook: Business email, calendars and scheduling.
- Microsoft Teams: Workplace messaging, video conferencing and collaboration.
- SharePoint: Document management and internal collaboration.
- OneDrive: Cloud storage and file synchronization.
- Microsoft Word, Excel and PowerPoint: Productivity and document creation.
- Microsoft Copilot: AI-powered workplace assistance.
These applications are interconnected through Microsoft’s cloud infrastructure.
One important component is Exchange Online, Microsoft’s cloud-based email platform. It supports email, calendars, contacts and other communication functions.
When Exchange Online experiences connectivity problems, the consequences can extend beyond the inbox.
Businesses that use Microsoft’s integrated ecosystem may suddenly struggle to access documents, communicate with colleagues, coordinate meetings or authenticate certain workflows.
That interconnectedness is a major advantage when everything works. During an infrastructure failure, however, it can become a significant weakness.
Latest Update: What Happened During the Microsoft Outage?
Microsoft Outlook hit with hourslong outage
The disruption began on November 12, with users reporting difficulties accessing Outlook and other Microsoft services.
Microsoft initially focused its investigation on connectivity problems affecting Exchange Online mailboxes in the Americas. The company subsequently acknowledged that customers in other regions could also experience problems.
According to Reuters’ November 12–13 coverage, the outage affected Microsoft’s workplace applications and also disrupted integrations used by OpenAI and Anthropic.
1. Outlook experienced widespread email disruption
Outlook was among the most visibly affected services.
Users reported:
- Inability to access their inboxes.
- Delayed incoming and outgoing emails.
- Problems connecting through web and mobile applications.
- Connectivity failures when accessing Exchange Online mailboxes.
Downdetector recorded nearly 130,000 reports of Outlook problems during the initial disruption.
It is important to understand that these numbers represent user-submitted reports, not a confirmed count of affected individuals.
2. Microsoft Teams experienced connectivity problems
Teams was also affected, creating difficulties for organizations that depend on Microsoft’s collaboration platform.
For businesses using Teams for meetings, internal communications and project coordination, the disruption meant that employees could not always rely on their usual communication channels.
Microsoft subsequently reported progress in restoring certain Teams-related functionality, although the broader disruption continued.
3. Microsoft Copilot and AI integrations were affected
One particularly important aspect of the incident involved AI services.
Microsoft Copilot experienced disruption alongside other Microsoft 365 applications.
OpenAI and Anthropic also reported problems involving their Microsoft 365 connectors.
This highlights an important distinction in modern AI infrastructure: an AI service can remain operational while a connected enterprise integration fails because its upstream provider is experiencing problems.
The incident demonstrates how dependent enterprise AI workflows can become on external cloud services.
4. Microsoft identified unexpected server failures
Microsoft initially described elevated infrastructure load across multiple regions.
The company later determined that a number of servers had unexpectedly become unavailable, placing additional pressure on the remaining infrastructure.
The recovery process involved restarting affected servers, redistributing traffic and applying infrastructure changes.
According to The Guardian’s November 13 report, Microsoft subsequently reported positive results after applying an upstream authentication and routing configuration component patch to part of its infrastructure.
The company also said it had no indication that the outage was caused by a cyberattack.
5. The disruption affected organizations beyond ordinary office workers
The consequences extended into several industries.
Reuters reported disruptions affecting government agencies, airlines, financial institutions and businesses.
Indian airlines including IndiGo, Akasa Air and Air India also reported problems with email support services.
Some financial organizations experienced communication difficulties severe enough to affect operational processes.
This demonstrates why cloud reliability is increasingly a business continuity issue rather than simply an IT concern.
Expert Insights: Why the Microsoft Outage Is Significant
The most important lesson from this incident is that cloud infrastructure failures rarely remain isolated.
Modern technology companies operate through interconnected networks of servers, authentication systems, applications and third-party integrations.
A problem affecting one critical infrastructure component can create secondary failures across multiple products.
The cascading failure problem
When some servers become unavailable, the remaining infrastructure must handle additional requests.
That creates an uncomfortable cycle:
- Some servers become unavailable.
- Traffic shifts toward the remaining infrastructure.
- The remaining servers experience additional pressure.
- Connectivity and performance deteriorate.
- Recovery becomes more complicated as systems are restarted.
This is a simplified explanation of the failure pattern described in Microsoft’s public updates.
Cloud concentration creates systemic risks
Organizations often choose Microsoft 365 because it reduces infrastructure costs and simplifies workplace management.
However, consolidating email, collaboration, file storage and business workflows within one ecosystem creates concentration risk.
The outage demonstrated that a single provider’s infrastructure problems can affect multiple operational functions simultaneously.
AI dependency introduces another layer of risk
The disruption involving Microsoft connectors used by OpenAI and Anthropic deserves particular attention.
Businesses increasingly connect AI assistants to email platforms, calendars, documents and internal databases.
These integrations create powerful workflows, but they also introduce dependencies that organizations must account for.
An AI assistant cannot reliably retrieve enterprise information when its upstream connector is unavailable.
Broader Implications: What the Microsoft Outage Means for Businesses
1. Cloud reliability is now a business-critical requirement
For many organizations, cloud platforms are no longer optional productivity tools.
They support customer communication, financial operations, internal reporting and business coordination.
When these systems become unavailable, the economic consequences can accumulate quickly.
Companies should evaluate cloud providers based not only on features and pricing but also on service reliability, incident transparency and recovery capabilities.
2. Businesses need alternatives to Microsoft 365
The incident reinforces the importance of having backup communication channels.
Organizations should consider:
- Secondary email communication systems.
- Independent messaging platforms.
- Offline document access.
- Alternative meeting arrangements.
- Emergency contact directories.
- Clearly documented business continuity procedures.
The goal is not necessarily to abandon Microsoft. It is to ensure that one provider’s disruption does not completely stop business operations.
3. AI businesses must rethink third-party dependencies
The Microsoft outage also highlights a growing challenge for AI companies.
As AI applications become deeply integrated into business systems, their reliability depends on the availability of external services.
This includes cloud hosting, authentication providers, enterprise connectors and data platforms.
For additional context, The Tech Marketer should internally link this article to its coverage of AI infrastructure and enterprise technology.
4. Microsoft’s reputation faces another reliability test
Microsoft’s productivity ecosystem has become deeply embedded in global business operations.
Repeated service disruptions could encourage enterprise customers to reconsider how much infrastructure they concentrate within one provider.
As Reuters noted in its coverage, the longer-term concern is whether repeated outages could influence IT departments’ decisions about relying too heavily on a single ecosystem.
Related History: How This Compares With Previous Technology Outages
The November 2026 incident is not happening in isolation.
Technology infrastructure has experienced several major disruptions that demonstrate the risks of centralized digital services.
Tech outage eases after widespread disruption | Reuters
TD Cowen Names Amazon Top Mega-Cap Internet Pick for 2026, Citing AI-Driven AWS Growth | Roic News
Microsoft | Saudi Arabia’s Trusted Cloud
8
The CrowdStrike outage of 2024
In July 2024, a faulty CrowdStrike software update triggered widespread Windows system crashes.
Airlines, hospitals, businesses and government organizations experienced major disruption.
The incident demonstrated how a single software update could affect organizations around the world.
Previous Microsoft cloud disruptions
Microsoft has also experienced earlier service interruptions involving Microsoft 365 and Azure.
Reuters reported that the November 2026 disruption was the second incident affecting Microsoft’s 365 services during the year.
The broader lesson is that even mature cloud platforms are vulnerable to configuration errors, infrastructure failures and unexpected dependencies.
The common thread
These incidents share an important characteristic.
Modern digital infrastructure is increasingly centralized, interconnected and dependent on automated systems.
That creates efficiency, but it also means that failures can spread much faster than organizations expect.
What Happens Next?
Microsoft’s immediate priority is restoring service stability and returning affected infrastructure to normal operation.
Its recovery efforts have included infrastructure patches, server restarts and traffic-management changes.
The company has indicated that it will provide further information through a post-incident report once the issue has been mitigated.
Several developments deserve attention over the coming days.
First, the final root-cause report. Microsoft needs to explain what caused the servers to become unavailable and why automated health checks failed.
Second, infrastructure safeguards. Customers will want to understand what changes Microsoft intends to make to prevent similar failures.
Third, enterprise customer confidence. Businesses will evaluate whether their existing backup and disaster recovery arrangements are sufficient.
Fourth, AI integration reliability. Companies using Copilot, ChatGPT and other enterprise AI products will increasingly need to assess the availability of their third-party connectors.
For now, Microsoft’s recovery efforts are encouraging, but the long-term test will be whether the company can prevent similar disruptions.
Conclusion
The November 2026 Microsoft outage is a reminder that even the world’s largest technology companies are not immune to infrastructure failures.
Outlook, Teams, Copilot and other Microsoft 365 services form part of the daily operating environment for millions of workers and organizations.
When those systems become unavailable, the consequences extend far beyond an inaccessible inbox.
The incident also highlights an important challenge for the next generation of enterprise AI. As businesses connect more workflows to cloud platforms and intelligent assistants, the reliability of underlying infrastructure becomes increasingly important.
Microsoft now has two jobs: restore customer confidence and demonstrate that its infrastructure can withstand similar failures in the future.
For businesses, the lesson is equally clear. Cloud technology makes operations more efficient, but resilience requires preparation for the moments when the cloud stops working.
Frequently Asked Questions
1. What caused the Microsoft outage in November 2026?
Microsoft identified unexpectedly unavailable servers that placed additional pressure on the remaining infrastructure. The company investigated infrastructure and configuration changes, but had not published a definitive root-cause report at the time of writing.
2. Was the Microsoft outage caused by a cyberattack?
Microsoft said it had no indication that malicious or cyber activity caused the disruption.
3. Which Microsoft services were affected?
The disruption affected Outlook, Exchange Online, Microsoft Teams, Copilot and other Microsoft 365 services, including certain SharePoint and OneDrive functions.
4. How many people were affected by the Microsoft outage?
Microsoft did not provide a confirmed number of affected users. Downdetector recorded nearly 130,000 reports of problems during the initial disruption across 74 countries and territories.
5. Was Microsoft Copilot affected?
Yes. Copilot experienced disruption, and Microsoft 365 connectors used by OpenAI and Anthropic also experienced problems.
6. Were Indian users affected?
Yes. The disruption had international consequences. Reuters also reported that Indian airlines IndiGo, Akasa Air and Air India experienced problems involving their email support services.
7. Is Microsoft Outlook working again?
Microsoft reported positive results from its recovery efforts on November 13. However, service recovery was uneven, with some users continuing to experience problems. Check Microsoft’s official Microsoft 365 Service Health information for the latest service updates.
8. How can businesses prepare for another Microsoft outage?
Businesses should maintain independent communication channels, offline document access, backup email arrangements and disaster recovery procedures. They should also identify critical workflows that depend on Microsoft 365.
Sources & References
1. CNN: Massive Microsoft outage disrupts businesses, schools and governments around the world, November 12, 2026.
2. Al Jazeera: Microsoft hit by global outages: What happened and why?, November 13, 2026.
3. CNBC: Microsoft outage hits Outlook. AWS and Google users also report issues, November 12, 2026.
4. Reuters: Microsoft outage hits Outlook, Teams and Copilot worldwide, November 12–13, 2026.
5. The Guardian: Microsoft scrambles to fix global outage affecting Teams and Outlook, November 13, 2026.